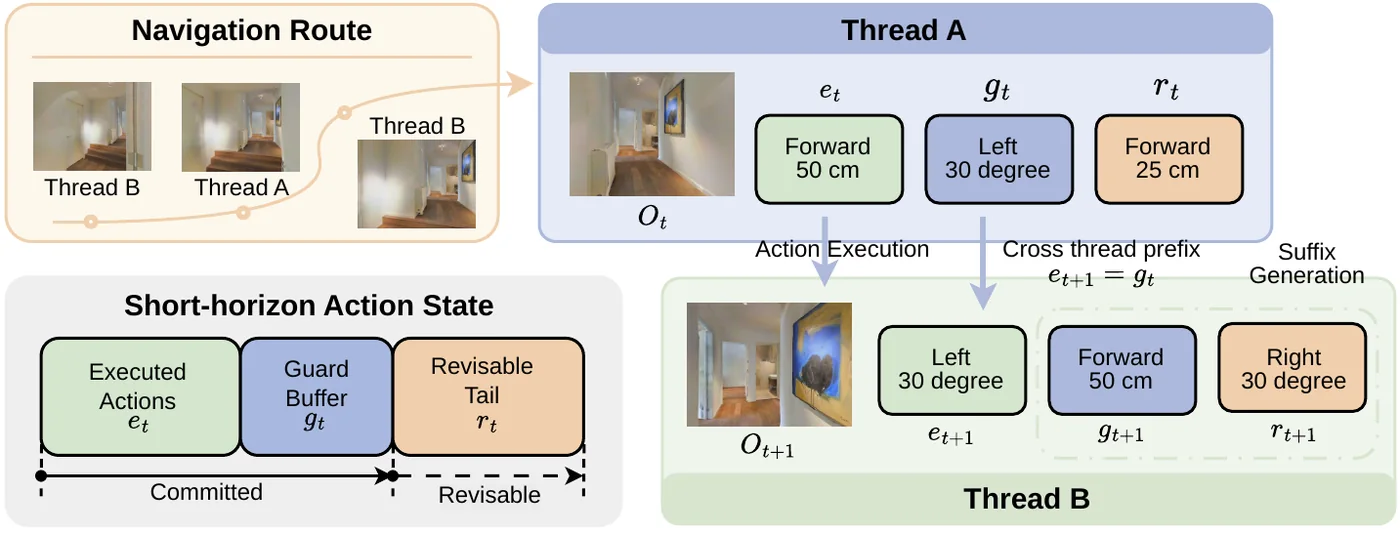
LiveVLN: Breaking the Stop-and-Go Loop in Vision-Language Navigation
A training-free runtime framework for embodied navigation that overlaps execution with observation refresh so agents move continuously instead of waiting on every inference step.
video understanding, Multi-model Agent and embodied navigation.
I am currently completing my M.S. in Computer Science at Southern University of Science and Technology (SUSTech), and will begin my Ph.D. study at Zhejiang University in Fall 2026.
A training-free runtime framework for embodied navigation that overlaps execution with observation refresh so agents move continuously instead of waiting on every inference step.
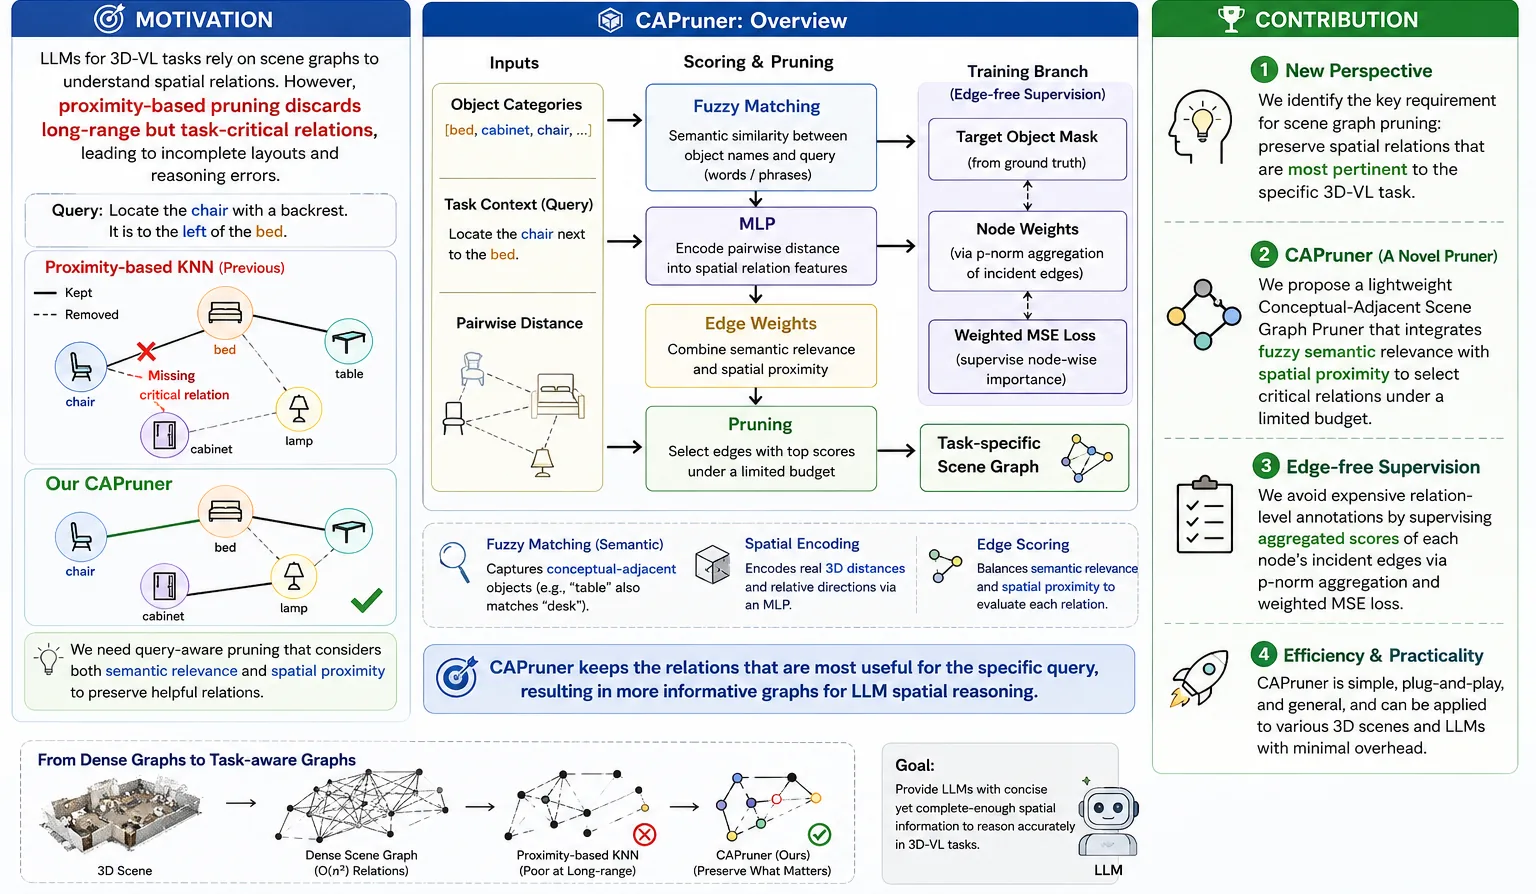
CAPruner prunes 3D scene graphs by combining fuzzy semantic relevance with spatial proximity, preserving task-critical relations for more reliable 3D spatial reasoning.
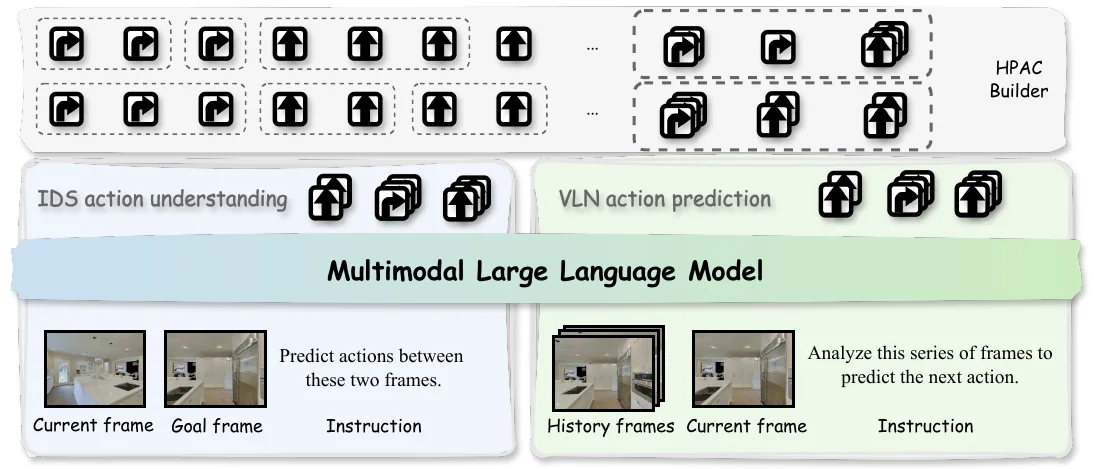
NaVIDA is a lightweight vision-language navigation framework that uses inverse dynamics supervision to learn action-grounded visual dynamics.
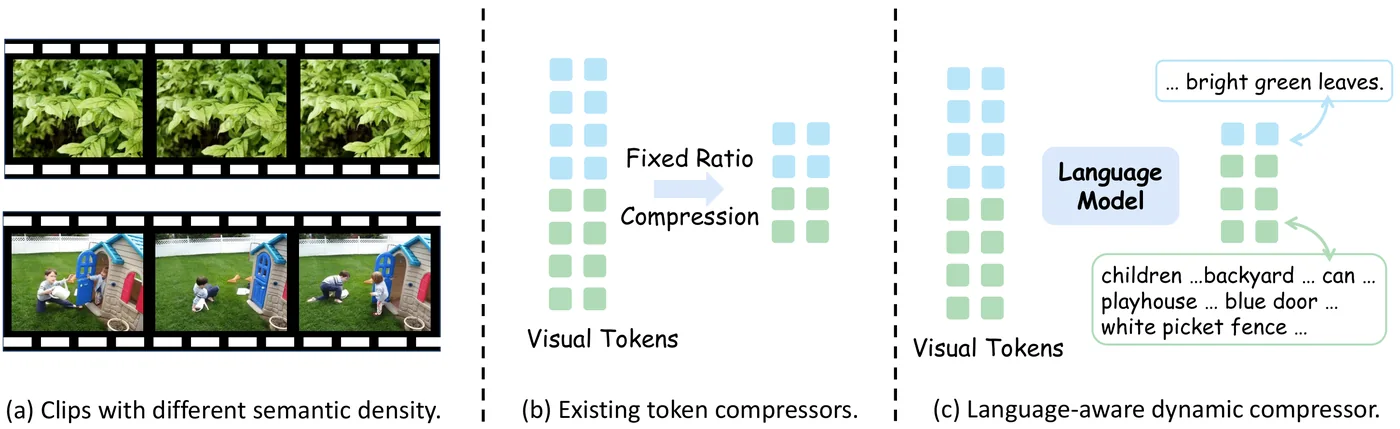
LangDC compresses video tokens dynamically with lightweight language experts, allocating more visual capacity to semantically rich clips and fewer tokens to simpler segments.