Overview
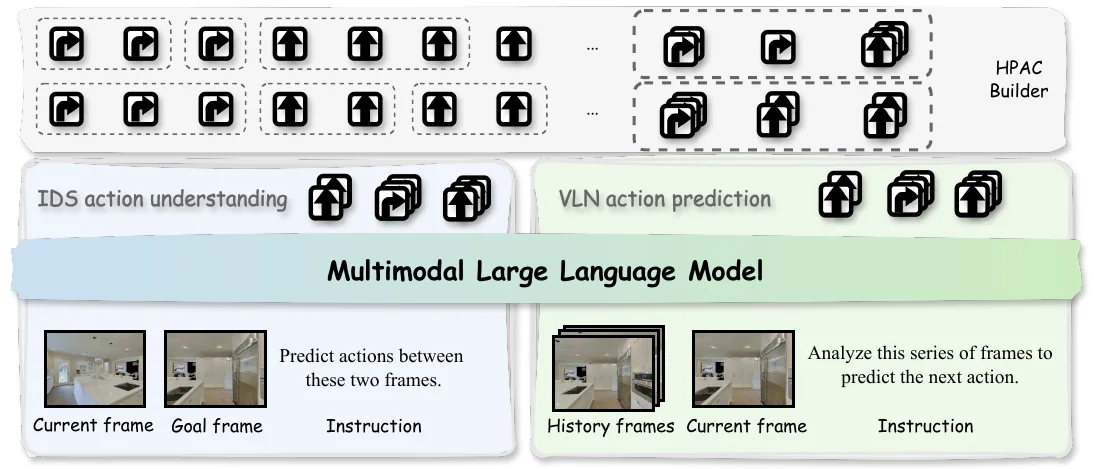
NaVIDA is a lightweight vision-language navigation framework for continuous environments. It uses inverse dynamics supervision to inject action-grounded visual dynamics into policy learning, helping the model connect what it sees with the actions that change its viewpoint.
The framework also organizes trajectories with hierarchical probabilistic action chunking, so navigation decisions can be learned and executed over multi-step action segments rather than isolated single-step predictions.
Key Ideas
- Inverse dynamics supervision for action-aware visual representations.
- Hierarchical action chunking for long-horizon navigation.
- A compact 3B-parameter design using only single RGB camera input.
- Practical training and evaluation support for VLN-CE style benchmarks.
Results
NaVIDA achieves strong VLN-CE performance with a 3B-parameter model. On the reported validation-unseen benchmarks, it improves over larger VLN baselines on both R2R and RxR while keeping the input setup lightweight.
Resources
BibTeX
@article{zhu2026navida,
  title={NaVIDA: Vision-Language Navigation with Inverse Dynamics Augmentation},
  author={Zhu, Weiye and Zhang, Zekai and Wang, Xiangchen and Pan, Hewei and Wang, Teng and Geng, Tiantian and Xu, Rongtao and Zheng, Feng},
  journal={arXiv preprint arXiv:2601.18188},
  year={2026}
}