Overview
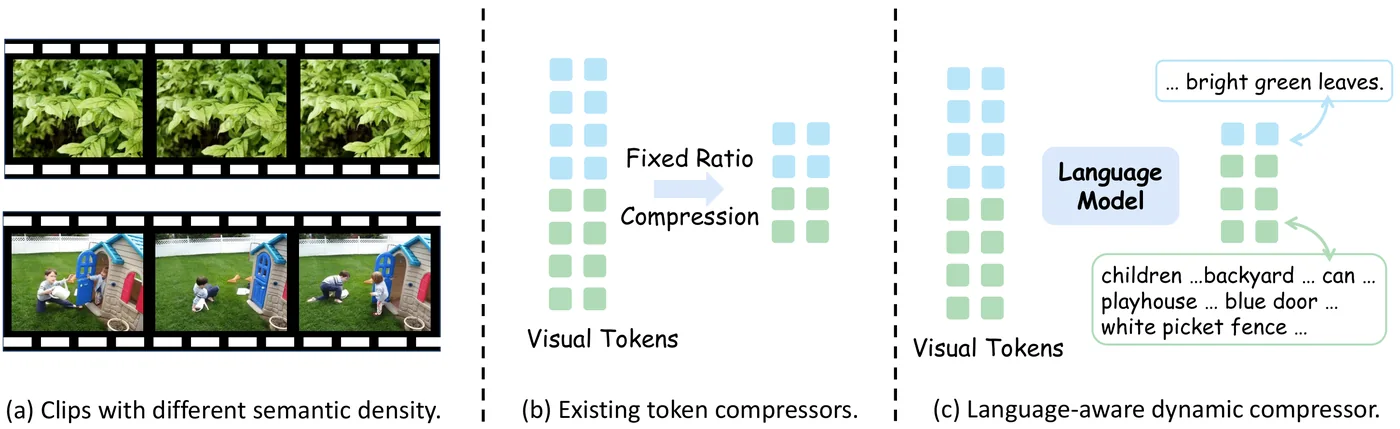
Large video-language models often process massive numbers of visual tokens, making inference expensive for long or visually dense videos. Existing fixed-ratio compression treats static clips and information-rich clips the same way, which can waste computation on simple segments while under-representing dense ones.
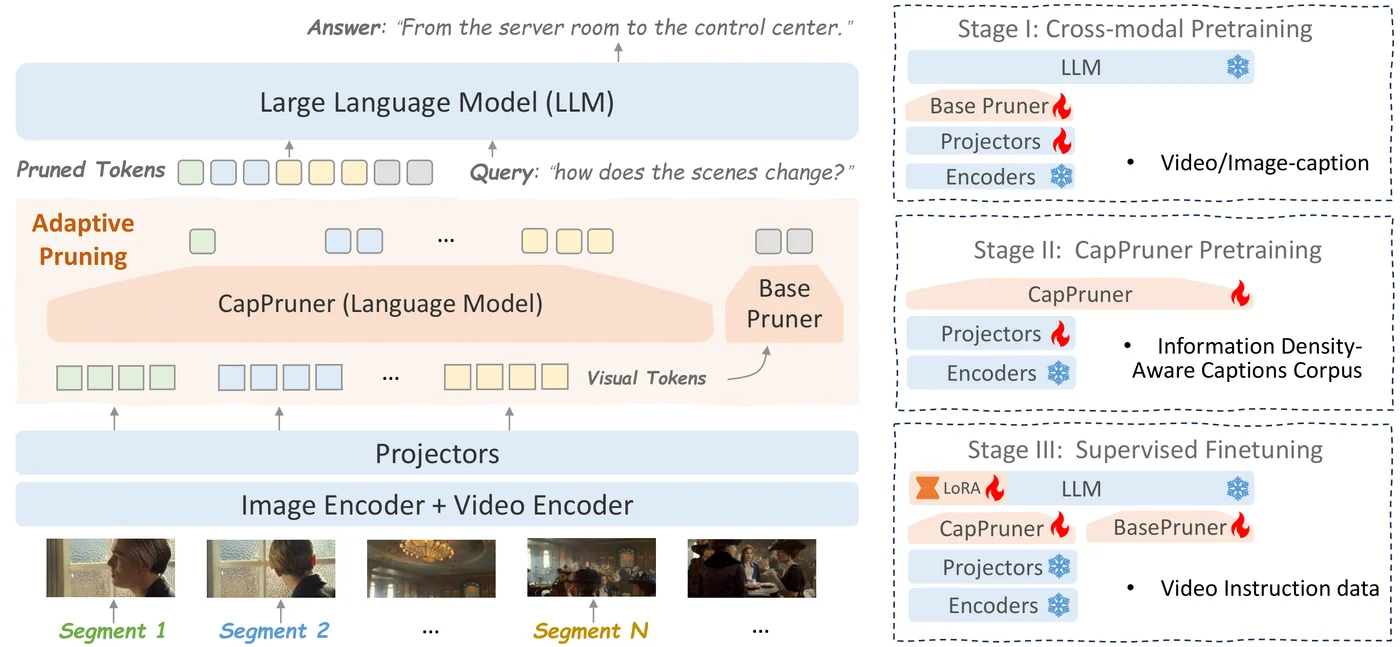
LangDC introduces a Language-aware Dynamic Token Compressor. It uses a lightweight language expert to describe video clips, converts descriptions into soft caption tokens as visual representations, and allocates compression budgets according to semantic density.
Key Ideas
- Language-guided dynamic video token compression.
- Soft caption tokens as compact visual representations.
- Semantic density-aware supervision for preserving reasoning-critical visual cues.
- Adaptive token allocation for information-rich and content-poor clips.
Results
LangDC reduces FLOPs by 49% compared with the strong VideoGPT+ baseline while maintaining competitive performance across video understanding benchmarks. Qualitative results also show that LangDC adjusts compression based on each clip’s semantic density.
BibTeX
@misc{wang2025seeing,
  title={Seeing More, Saying More: Lightweight Language Experts are Dynamic Video Token Compressors},
  author={Xiangchen Wang and Jinrui Zhang and Teng Wang and Haigang Zhang and Feng Zheng},
  year={2025},
  eprint={2509.00969},
  archivePrefix={arXiv},
  primaryClass={cs.CV}
}